The Complete Guide to llms.txt: Should You Care About This AI Standard?
 Bob Mitro
llms.txt is a tiny Markdown file with a surprisingly large argument attached to it. When we first covered it in 2025, 844,473 live sites already had one. What we did not have was a clear answer from the companies building the biggest AI products. Were their systems reading these files, or were website owners preparing for a standard that might never arrive?
We know more now. The proposal is at version 2, Chrome Lighthouse can check the file, and OpenAI, Anthropic, Cloudflare, and Stripe publish indexes for their developer documentation. Google has answered the SEO question too: Search ignores llms.txt, including for its generative AI features.
The file has a smaller job than its early advocates imagined. On a large documentation site, it can point an agent or coding assistant toward the right guide. On a five-page brochure site, the case is difficult to make.
Updated October 18, 2026: This version covers the v2 proposal, Google's guidance on llms.txt, current implementations, OpenAI and Anthropic crawler controls, Chrome Lighthouse's optional check, and version 1.2 of Publii's LLMS.txt Generator.
What changed in 2026
Most of the early debate was speculation. Supporters expected AI systems to adopt a simple website index; skeptics saw a file with no committed reader. Our original article reflected that uncertainty and, in a few places, treated weak signals as stronger evidence than they were. This update corrects that.
Google answered the SEO question
Google's answer is about as clear as these things get. Its guide to generative AI features in Search says Google Search does not use llms.txt. The file brings no ranking boost and no penalty, whether the result appears as a traditional link, an AI Overview, or in AI Mode.
If Google traffic is your only reason for creating the file, spend that time on the website instead: improve the content, internal links, crawlability, and page experience.
The proposal reached version 2
Jeremy Howard published the first proposal in September 2024 and released version 2 in August 2026. An index can now sit at the root of a domain or inside a subpath, covering only that part of the site. The updated proposal also explains how an HTML page can advertise its Markdown version and the index that describes it.
It is still a community proposal rather than an IETF or W3C standard. Tools are free to support it, ignore it, or use only part of it.
Adoption grew, partly through automation
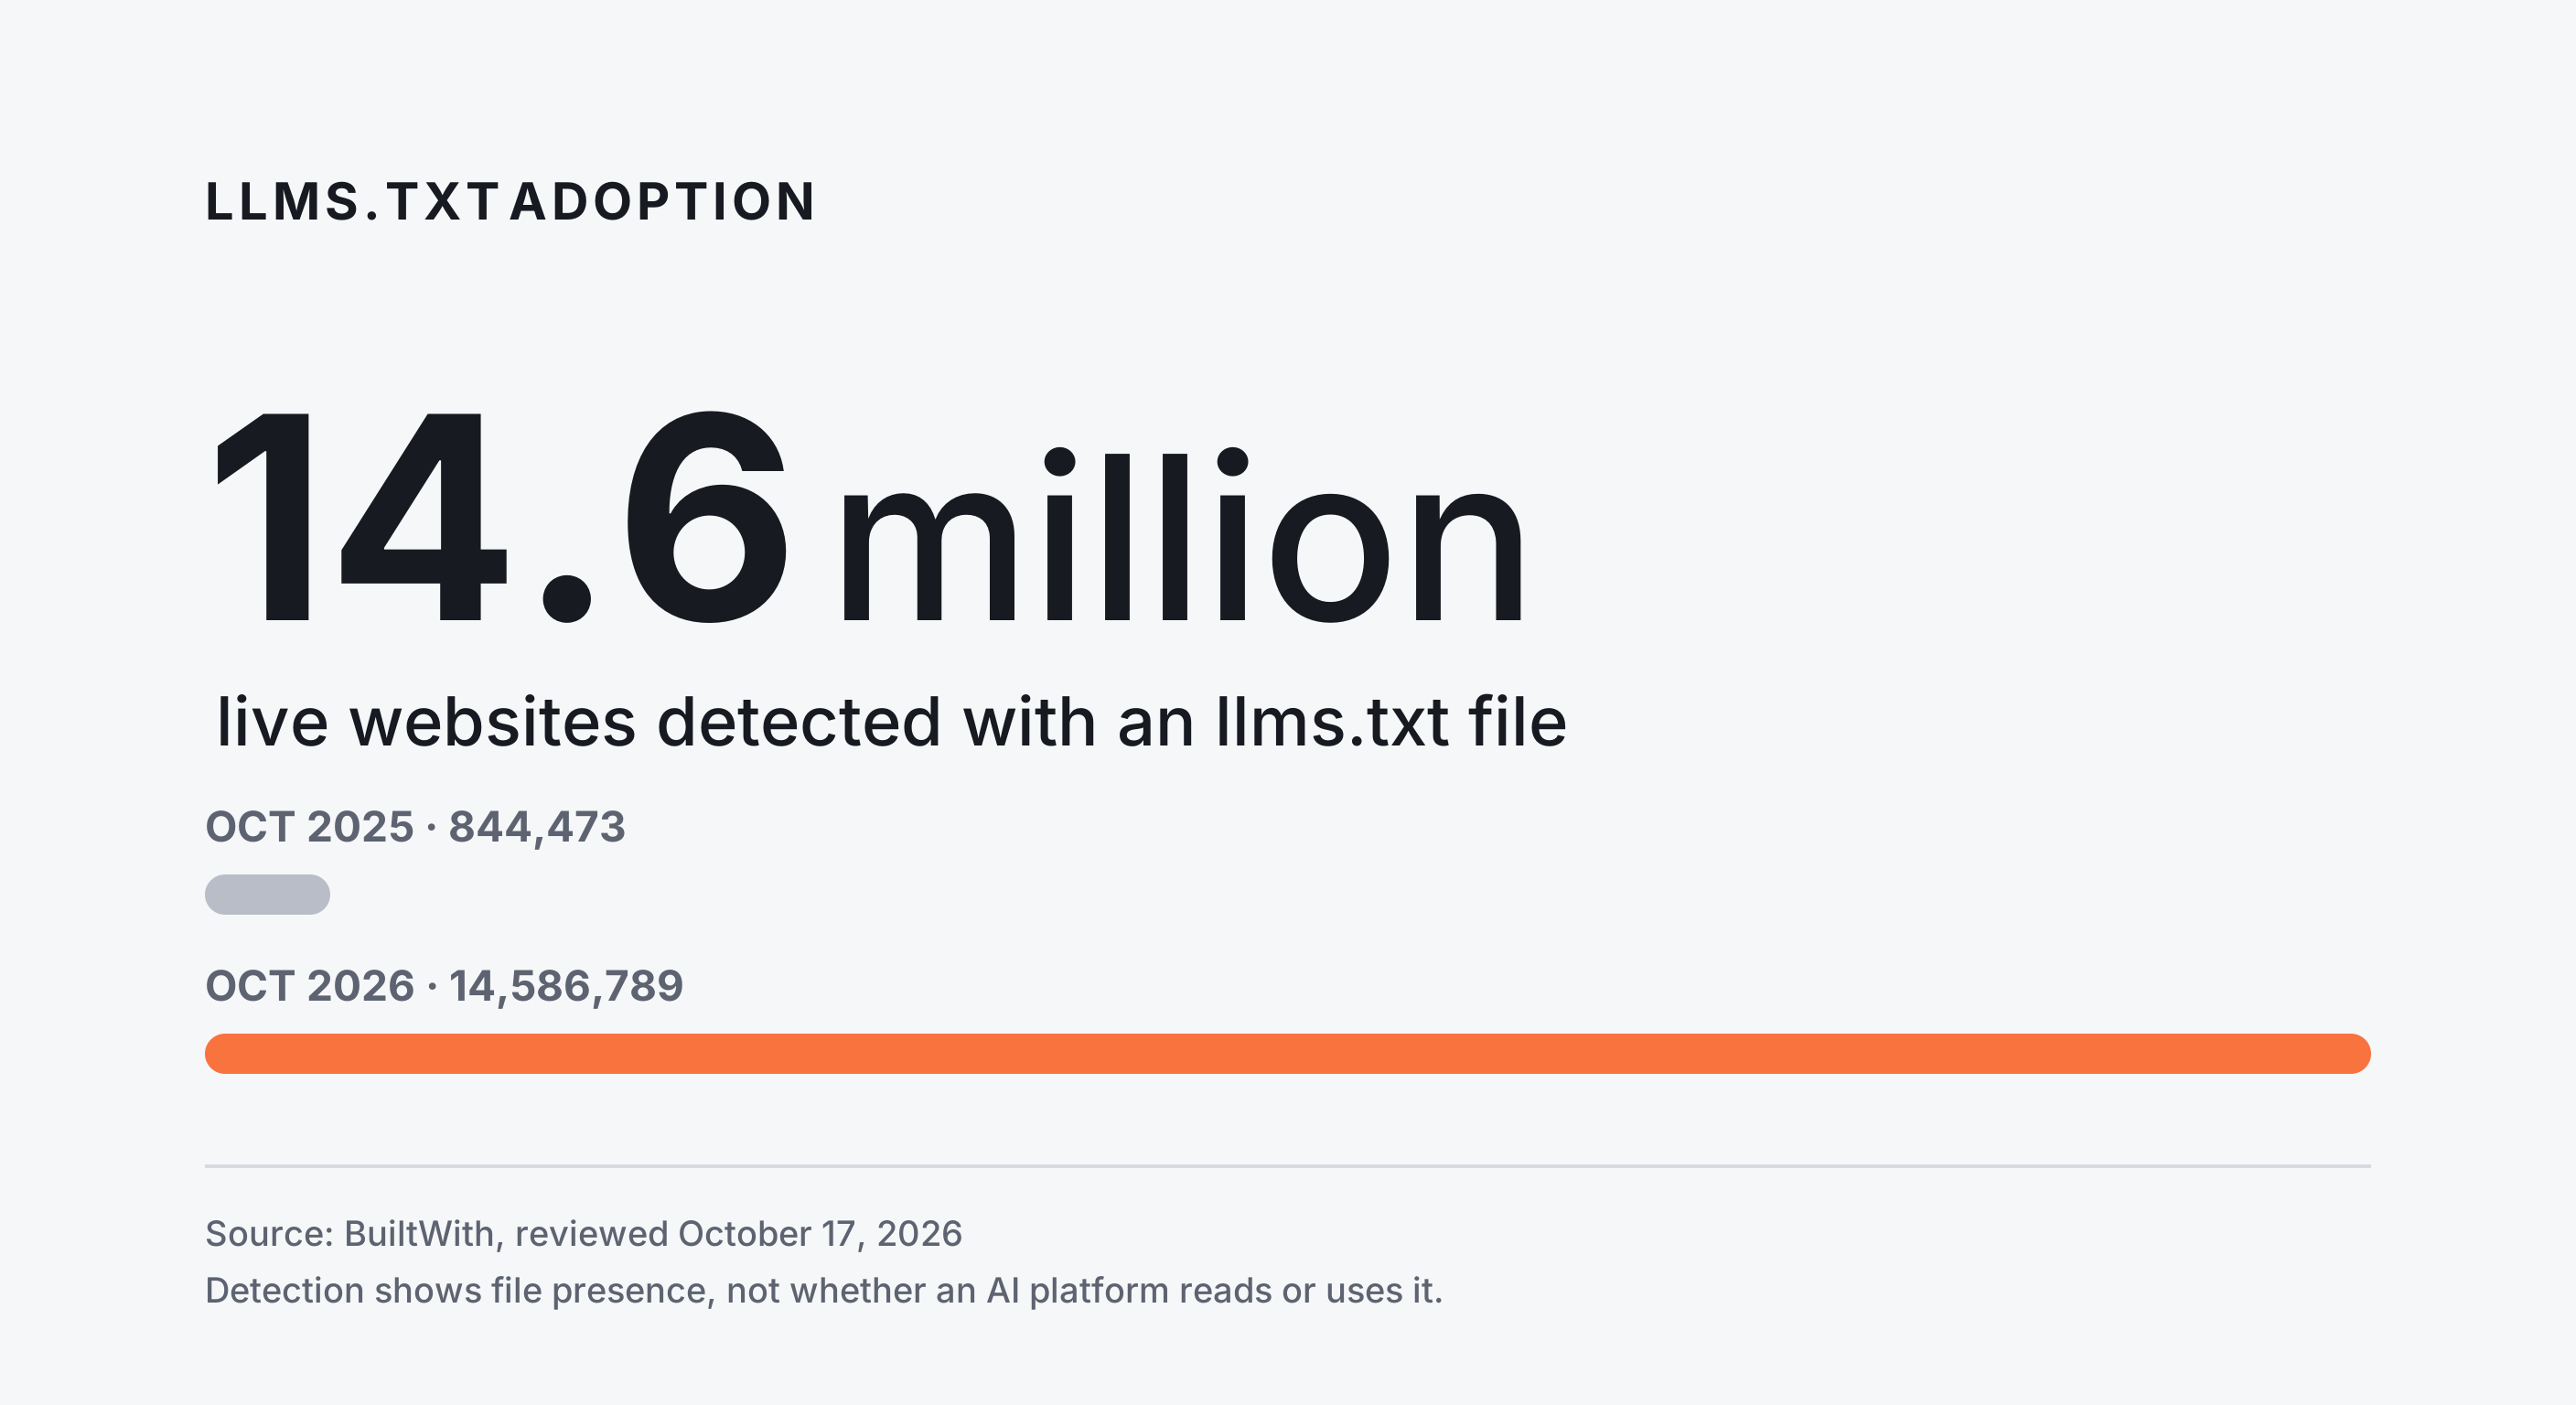
14,586,789 is the kind of number that begs for a giant chart. We made one, but it needs an asterisk. That is how many live websites BuiltWith reported when we checked on October 17, 2026. Our October 2025 snapshot showed 844,473.
Part of the jump comes from automation. Documentation and hosting platforms can add the file to every site they publish; Mintlify does this automatically. BuiltWith sees the files, not the editorial decisions behind them or the agents that may read them.
Chrome Lighthouse now has an optional llms.txt audit among its agentic browsing checks. It verifies that an available file can be retrieved. A missing file receives “not applicable,” not a failed audit.
What llms.txt does
Think of a documentation site with hundreds of guides, API references, changelog entries, and product pages. A coding assistant looking for the current authentication guide has to find the right section before it can read the answer. Navigation, scripts, banners, and repeated page elements add more material to process along the way.
An llms.txt file gives that tool a short Markdown index prepared by the site owner. The file introduces the project, groups useful resources, and can link directly to clean Markdown versions of individual pages. A compatible agent can read the index first and decide which page it needs.
This describes retrieval, not access control. Three separate activities are often mixed together in conversations about the file:
- Training uses collections of data to develop or improve a model.
- Search and retrieval find current pages that can support an answer.
- User-directed fetching opens a page because a person or agent requested it during a task.
llms.txt does not grant or deny permission for any of them. Crawler preferences belong in robots.txt, while private information still needs authentication.
What the v2 file looks like
The format is plain Markdown. Only the H1 project name is required. Most useful files also include a short description and a few H2 sections with links.
# Example Studio

> A small design studio building accessible websites for local organizations.

Use the project guides for current services and delivery details.

## Key resources

- [Services](https://example.com/services.md): Website design and development services
- [Project process](https://example.com/process.md): How discovery, design, and delivery work
- [Accessibility policy](https://example.com/accessibility.md): Standards used across client projects

## Optional

- [Journal](https://example.com/blog/): Articles and studio news
The Optional section is reserved for secondary material that a tool may skip when context is tight. Descriptions should tell the reader what is on the linked page instead of echoing its title.
Version 2 provides two ways to expose Markdown alternatives. You can append or substitute .md in the page URL, such as /guide.html.md or /guide.md. You can also advertise the Markdown version with rel="alternate" type="text/markdown" and point to the relevant index with rel="describedby". These relations work in HTML or an HTTP Link header.
You may also come across llms-full.txt. It is exactly what the name suggests: the documentation gathered into one large file. That can be handy when someone deliberately loads the whole thing into an AI tool. It can also become enormous and go stale quickly, which is why I prefer a concise index for routine navigation.
Who's using llms.txt?
If you want to see llms.txt doing a sensible job, start with technical documentation. Finding the correct guide or API reference can save several dead ends.
- OpenAI's developer index points to separate indexes for the API, Codex, ChatGPT apps, the Cookbook, and other documentation sets. It also links to Markdown versions of individual pages.
- Anthropic's developer index organizes Claude API documentation and links to Markdown pages across its multilingual documentation site.
- Cloudflare and Stripe publish indexes for large developer documentation collections.
- Mintlify generates
llms.txtandllms-full.txtfor every documentation project hosted on its platform.
The pattern is hard to miss: these are large documentation collections, not small marketing sites. The next question is whether the AI providers read indexes published elsewhere on the web.
What providers have documented
| Provider | Published information | Practical meaning |
|---|---|---|
| Google Search | Google says Search ignores llms.txt. | The file has no positive or negative effect on Google visibility or rankings. |
| OpenAI | OpenAI documents separate crawlers for search, training, and user-directed visits. Its developer site publishes an llms.txt index. | OpenAI uses the format for its documentation but does not list it as a requirement for ChatGPT Search inclusion. |
| Anthropic | Anthropic documents ClaudeBot, Claude-SearchBot, and Claude-User. Its developer documentation has an llms.txt index. | Anthropic publishes the format but has not promised that Claude Search will read every site's file. |
| Chrome Lighthouse | Lighthouse checks whether an available file can be retrieved. | The audit is optional, and a 404 is marked not applicable. |
OpenAI and Anthropic use the format on their own documentation. Neither company documents it as an input that ChatGPT Search or Claude Search reads across the public web.
What can you expect from it?
An agent that opens a current, well-organized llms.txt file gets a map chosen by the site owner. On a large documentation site, that can shorten the route to the right guide. You can also give the file directly to a coding assistant when you want it to work from a curated set of sources.
Our earlier article leaned too heavily on isolated case studies and crawler logs. We are correcting that here. A log entry can confirm that a bot fetched the URL, but it cannot show that the file changed an answer. There is still no provider-independent evidence of higher AI citations, referral traffic, answer accuracy, or search rankings after publication.
The index does not “train AI on your website.” Model training, search indexing, live retrieval, and a user asking a tool to open a page are separate processes with separate crawler rules.
Where it fits alongside existing web files
robots.txt expresses crawler access preferences, while sitemap.xml helps search engines discover URLs. Schema.org markup describes products, organizations, articles, and other entities in a vocabulary that supported search features understand. Each has a documented job and established consumers.
llms.txt is a curated reading list for tools that choose to use it. Your sitemap can keep its job. The new file cannot block a training crawler, make a page eligible for a rich result, or compensate for poor navigation on the website itself.
When the file is worth adding
For technical documentation, I would use it when the index can be generated automatically. Readers already bring API and product questions to coding assistants, and a maintained file gives those tools a sensible place to start. A large editorial archive can benefit for the same reason.
For a five-page brochure site? I would spend the hour elsewhere. There is little to simplify, especially if the HTML and navigation are already clear. The file should also wait when someone would have to maintain a second set of summaries by hand.
The test I use is simple: name the workflow. Perhaps a coding assistant needs to find the current installation guide, or a support agent needs the right troubleshooting page. If you cannot name a task, do not add the file yet.
Building a file you can keep current
If you decide to publish an index, keep the first version small. A short, accurate file is more useful than a comprehensive export that becomes stale.
- Choose the audience and the task the file should support.
- Select the pages that help with that task rather than copying every URL from the sitemap.
- Write a short description for each link and check that it agrees with the linked page.
- Use stable, absolute URLs. Add Markdown alternatives only when your publishing process keeps them current.
- Make sure the URL returns the text file with a successful response instead of an HTML error page.
- Rebuild the index when content is published, moved, hidden, or removed.
- Give an agent the index as its starting point and watch which links it follows. Compare its answers with the source pages.
Using llms.txt with Publii
Writing the first index by hand is easy. Remembering to fix it six months later, after posts move and tags change, is the part nobody looks forward to. Publii already knows which posts, pages, tags, and featured items belong to a site, so the LLMS.txt Generator can rebuild the file during normal site generation.
You choose which sections to include, change their labels, add introductory notes, and select resources manually when the automatic groups are not enough. Recent posts, featured posts, main tags, and pages can all feed the index. When the site is regenerated, the file is rebuilt with it.
Version 1.2 works with the Markdown for AI plugin. If a post or page has a Markdown version, the generated index can link to it. Otherwise, it keeps the regular HTML address. The plugins also work independently.
The plugin handles the boring part: keeping the index in step with the site. It does not change Google's answer about rankings. If you need an index for documentation or an agent workflow, inspect Publii's own llms.txt file and use it as a starting point. If you do not have that use case, leave the plugin off.
Work on the pages first
Before worrying about a machine-readable index, open the pages it would link to. Are they accurate? Can a visitor find them without guessing? Do the headings and internal links make sense? Most websites will get more value from fixing those basics, along with visible authorship, dates, and corrections.
Crawler controls also need to match your goal. OpenAI uses OAI-SearchBot for ChatGPT search visibility and GPTBot for potential model training. Anthropic separates Claude-SearchBot, Claude-User, and ClaudeBot. Blocking or allowing one process does not automatically make the same choice for the others.
Google's guidance on AI-assisted writing focuses on the quality and purpose of a page rather than whether every sentence was typed without assistance. Original reporting, experience, and useful analysis matter. Producing large numbers of interchangeable pages for search manipulation is where automation becomes a problem.
Would I add llms.txt?
On a documentation site with automatic generation, yes. On a small marketing site where somebody has to maintain it by hand, no. Publii users sit in a practical middle ground because the plugin removes most of the upkeep, but the file still needs a purpose.
Do not install it for Google rankings. Google ignores it. For an agent workflow, run a simple test: give the tool the index, ask questions that require different parts of the site, and see whether it reaches the right sources. If it does, keep the file. If it does not, you have lost an experiment, not a strategy.